
## A pattern we kept seeing
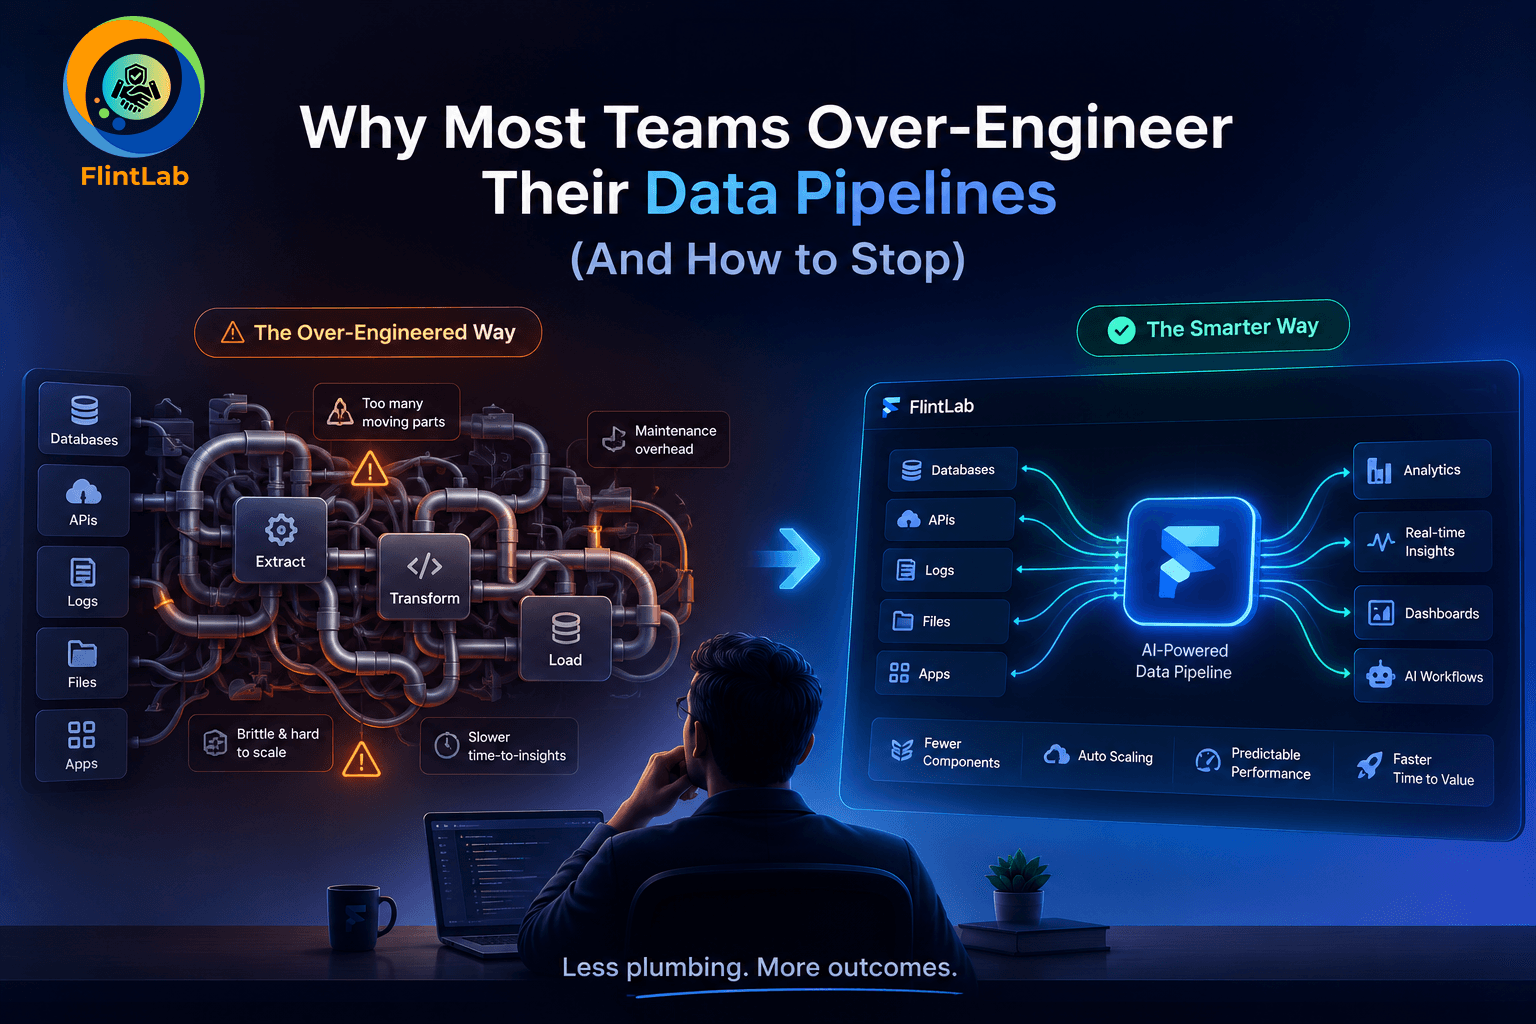
We looked at 500 customer pipelines built on FlintLab over the past year, expecting to find that the most successful teams had built the most sophisticated systems. We found the opposite. The pipelines with the fewest incidents, the fastest onboarding time for new engineers, and the least maintenance overhead were, almost without exception, the simplest ones in our dataset.
### Premature abstraction
It's tempting to build a generic, configurable framework the first time you need to move data from A to B "just in case" you need to move data from C to D someday. Most of the time, that day never comes, and you're left maintaining an abstraction layer for a use case that doesn't exist.
### Defensive complexity
Teams that have been burned by a production incident often respond by adding layers of validation, retries, and fallback logic sometimes three or four deep for failure modes that occur once a year, if ever. Each layer adds a place where something new can break, and a piece of logic the next engineer has to understand before they can safely change anything.
### Optimizing before measuring
We saw several pipelines with elaborate caching, batching, and parallelization logic built in from day one for data volumes so small the entire job could run in under a second without any of it. Complexity added ahead of an actual performance problem is complexity paid for with no return.
## What the simplest, most reliable pipelines had in common
- **One clear responsibility per step.** Steps did one thing, named clearly, with no hidden side effects.
- **Linear where possible.** Branching and conditional logic were used sparingly, only where the business logic genuinely required it.
- **Observability over prevention.** Instead of trying to anticipate every failure mode in advance, these teams built good logging and alerting, and fixed issues quickly when they did occur rather than trying to engineer every possible issue away upfront.
- **Deletion as a habit.** The best teams periodically removed steps and logic that were no longer earning their keep, rather than letting every addition become permanent.
## How to simplify an existing pipeline
If you suspect your own pipeline has drifted toward unnecessary complexity, a few questions can help:
1. When was the last time this piece of logic actually mattered in production?
2. Could a new team member understand this step without asking someone else?
3. If you deleted this abstraction and hardcoded the one use case you actually have, would anything break?
If the honest answer to #3 is "no," that's usually a sign the abstraction can go.
## Simplicity is a feature
None of this is an argument against sophistication where it's earned — some problems genuinely are complex. But complexity should be pulled in by a real, current requirement, not pushed in ahead of one. The teams getting the most out of their pipelines aren't the ones with the most machinery. They're the ones who've been disciplined about keeping only what's earning its place.